

Customer Support
Engage users in natural, personalized conversations using your knowledge base.
https://api.vivix.ai as the base URL and carry the Authorization: Bearer <API_KEY> header. Every REST response is wrapped in {"code": 0, "message": "success", "data": {...}} — the business fields live in data.
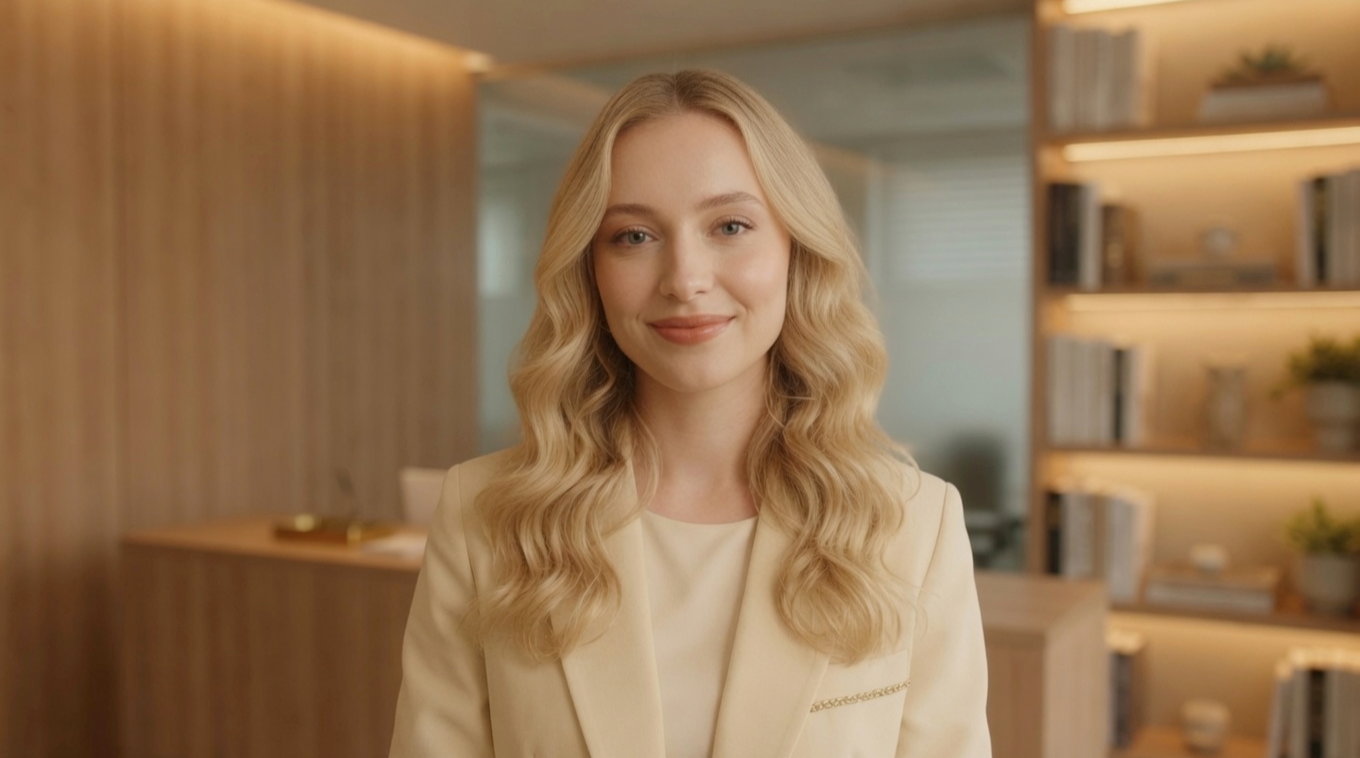
Claire is a customer support avatar who sits in an office, facing the camera: she answers product questions, troubleshoots integration issues, and keeps a calm, professional expression and tone throughout the conversation. This scenario covers the most typical Streaming Avatar usage — conversation-driven: you write what the user says into the conversation context, the avatar generates a reply from that context, and the reply streams out in real time as speech, rendered video, and word-by-word captions.
Core Concepts
A Streaming Avatar session is built from four objects:
Three channels carry the flow, each with its own job:
- REST (
/v1/realtime-avatar/sessions) — the session lifecycle: create, retrieve, close. - WSS control channel (
control.url, pointing at/v1/realtime-avatar/control) — sends and receives conversation / response / session events. - Media stream (chosen by
delivery.media.transport; currently supportstrtcandagora) — carries generated avatar audio and video downstream and user microphone audio upstream.
Step 1: Create a Session
UsePOST /v1/realtime-avatar/sessions to initialize the session’s selectable avatars, default avatar, voice pipeline, and conversation defaults. avatars[] defines Claire’s appearance and persona: visual.source_images provides the reference images (they decide what the avatar looks like and what scene she is in), instructions writes the persona, and the top-level pipeline_config.tts_config selects the voice used for generated speech.
Request
Model choice. The
model field also accepts the lighter vivix-a1-stream-lite variant — see Models for the differences. For the full field tables, see the Sessions API.Response
session_idcontrol.urlandcontrol.client_secretdelivery.media- the server-side effective
session.mode/active_avatar_id/source_image_id
Step 2: Connect Media, Then the Control Channel
Invideo_avatar mode, join the TRTC media stream first. The default demo requests microphone permission after the user clicks Start and must run over HTTPS. Convert sdk_app_id to a number, pass the string room id as strRoomId, register remote video handlers before entering the room, and subscribe only to publisher_user_id:
TRTC setup
control.url and append the session token as a token query parameter:
Browser Control WSS
control.client_secret is the browser-safe, session-scoped control credential (never your API key). Do not log it or the complete control.url out of logs as well.Step 3: Accept Voice and Text Input
The default demo keeps both a microphone button and a text box. Both input paths share the same conversation and response output events.Voice Input
Step 1 enablesturn_detection.type: "server_vad" and audio transcription. startLocalAudio publishes microphone audio to the same TRTC room. When the user finishes speaking, the server runs ASR, appends the user conversation item, and creates a response automatically. Voice turns do not send conversation.item.create or response.create from the client:
Voice turn
Text Input
Useconversation.item.create to write a submitted text message into the conversation context:
conversation.item.create
conversation.item.created:
conversation.item.created
response.create. Do not write conversation.item.create and response.create back-to-back in the same send loop; the response could otherwise start before the context item is confirmed.
Two things to note:
conversation.item.createfor typed input only adds an item to the context — it does not automatically make the avatar speak. After the acknowledgment, sendresponse.create. In server_vad mode, the server performs both steps for voice input.- When
previous_item_idis omitted, the item is appended to the end of the context; pass it only when you need to insert after a specific item.
Step 4: Trigger a Reply for Text Input
After receiving conversation.item.created for typed input, sendresponse.create. The current active avatar generates a reply from the conversation context:
response.create
scheduling_policy defaults to interrupt (interrupt the current response and run the new one immediately) — see the queueing and interruption section of the Live Performance sample case. Server events then arrive in order on the control channel. For captions, use response.output_text.delta for word-by-word display and response.output_text.done for the final text:
response.output_text.delta
response.output_text.done
response.done
response.render.started/response.render.stopped: the avatar audio and video for this response start / stop rendering on RTC.response.done: the Response resource and its logical output stream are finished — the Vocal and Visual attached to the Response are all complete. It fires no matter which terminal state the response ends in; read the final status fromresponse.done.response.status.- In
video_avatarmode, treatresponse.doneas the signal that a round of avatar output has fully finished.
Step 5: Close the Session
The default demo must provide an explicit End session button. If a response is still active, wait for its final response.done event, then close WSS, stop and destroy TRTC, and ask your own backend to close the session so remote resources are released. The Close Session REST call carries your VIVIX_API_KEY and must run on your backend — never from the browser:Close session
Expression and Emotion: Writing Instructions
Claire’s expression and emotion are not driven by a dedicated interface — they come from how you writeavatars[].instructions. Write instructions as “how the character speaks”, not “how the system works”:
avatars[].instructionsdefines only the persona and tone — it grants no tools or business data access. Put the task goal of the current application inconversation.instructions, and one-off directives for a single generation inresponse.instructions(priority: avatar < conversation < response; see Write spoken instructions).- For production integrations, explicitly constrain the output to plain spoken language: only what the character would actually say out loud — no character names, no narration, no action descriptions, no stage directions, no Markdown, no JSON, no parenthetical asides, no emojis.
- When the user asks the avatar to perform an action, do not let the model describe the action in text — actions are driven by
response.script.visual.promptor session state (see the Live Performance sample case).
The recommended constraint block (append it to the end of your instructions):
Constraint template
Sample reply
Minimal Runnable Event Sequence
Putting the steps together, the default demo connects in this order:Connection
Text input
Voice input
Response output
Cleanup
Next Steps
- Live Performance — the other sample case, built around actions: use
response.scriptto directly drive singing, dancing, and fixed lines. - Script speech and performances — directed movement and scripted audio.
- Change outfits and scenes — switch the avatar image during a session.
- Add tools to the character — function calls.
- API References · Sessions — REST endpoints and parameter details.
- API References · Client events / Server events — the complete event mechanism.
- Streaming World — realtime interactive video worlds driven by the W-series models; coming soon.